eDiscovery involves enormous volumes of information, from emails and business documents to chat messages, spreadsheets, and other electronically stored information (ESI). Reviewing every collected file can consume significant time and resources, but reducing the volume too aggressively can leave important evidence undiscovered.
Data culling helps legal teams manage this challenge. By combining targeted filtering, document analytics, and quality control, organizations can reduce unnecessary review while preserving potentially relevant information and meeting their discovery obligations. The goal is not simply to collect fewer documents. It’s to make informed, documented decisions about which data requires attention and why.
“Data culling is most effective when it starts with a clear understanding of the case, not just a goal of reducing document volume,” said Josh Burke, Avalon's Director of Legal Technology Operations. “The right approach combines technology, sound judgment, and quality control to help legal teams focus their resources where they matter most.”
What is Data Culling in eDiscovery?
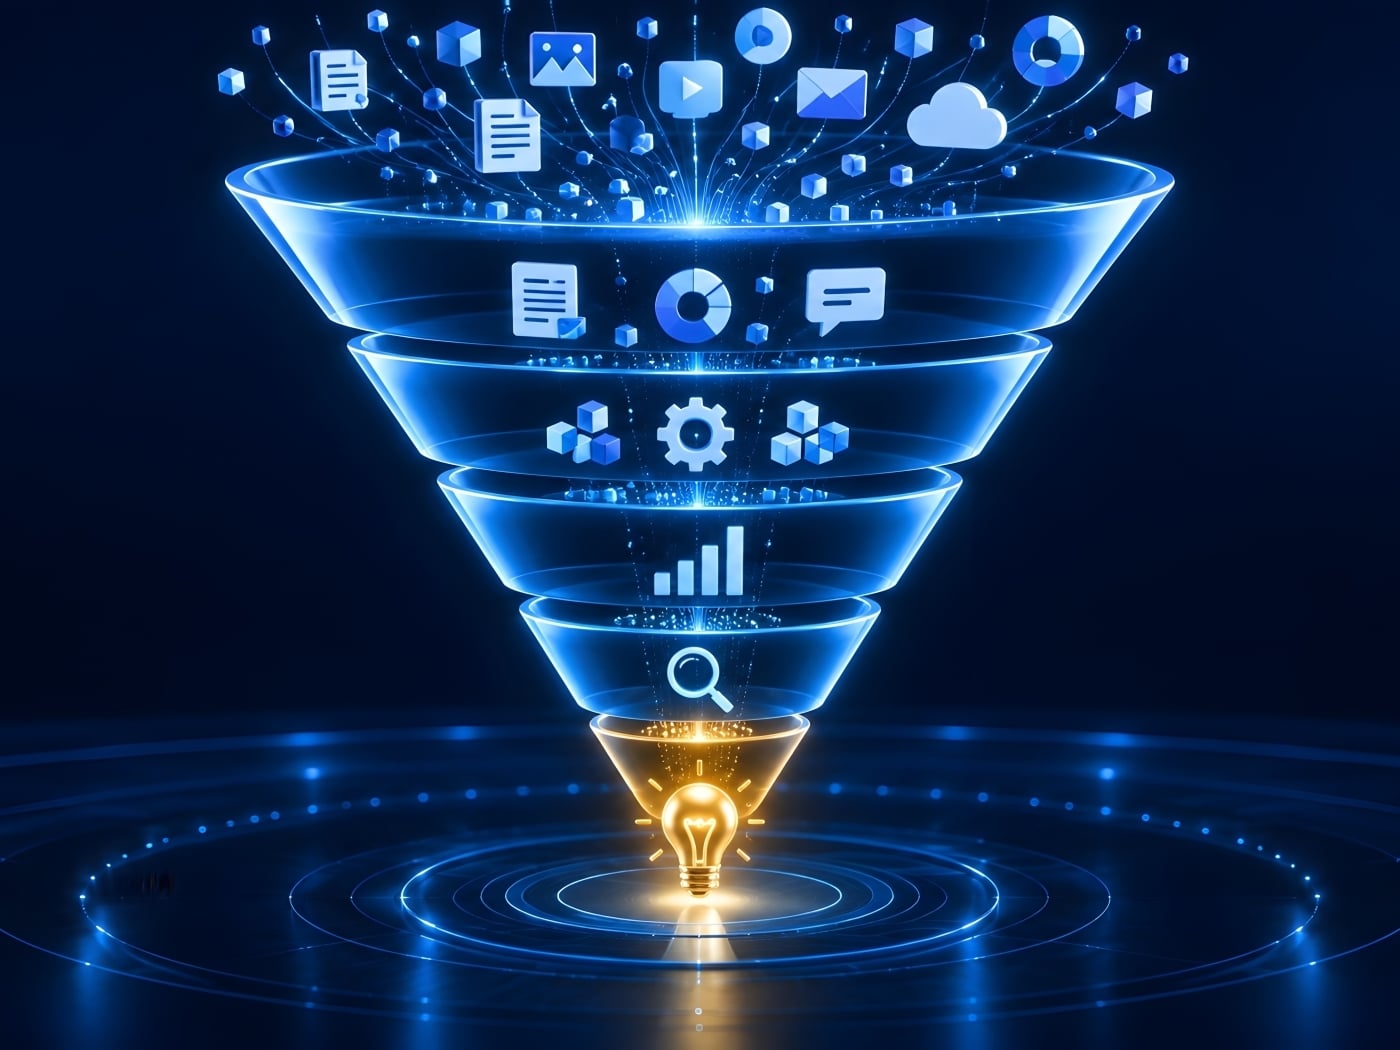
Data culling is the process of narrowing a collected dataset before document review by removing or separating information that falls outside agreed discovery parameters. It typically takes place during eDiscovery processing, after potentially relevant data has been collected and before attorneys begin reviewing documents for responsiveness, privilege, and other issues. Techniques range from basic metadata filtering to advanced analytics and AI-assisted document analysis.
Effective culling reduces hosting expenses and review hours, allowing you to run the production faster. However, the process must account for the scope of discovery, preservation obligations, applicable court orders, and relevant privacy or regulatory requirements.
Federal Rule of Civil Procedure 26(b)(1), for example, limits discovery to nonprivileged information that is relevant to a party’s claims or defenses and proportional to the needs of the case. Proportionality considers factors such as the importance of the issues, the parties’ resources, and whether the burden or expense outweighs the likely benefit. These principles can guide data reduction, but they do not authorize indiscriminate deletion of potentially relevant evidence.
Five Analytics Techniques That Make Culling More Effective
eDiscovery platforms offer several ways to identify redundant, irrelevant, or potentially responsive information. Each technique serves a different purpose, and the strongest approach often combines multiple methods.
1. Date, custodian, and file-type filtering
Basic metadata filters are often the first step in data reduction. Metadata includes information about a file, such as its creation date, sender, recipient, or file type. These filters can help isolate documents within the relevant time frame, identify records associated with key custodians, and exclude file types that fall outside the agreed scope. Before applying exclusions, however, teams should confirm that the criteria align with the discovery plan and that relevant exceptions have been considered.
2. Deduplication and email threading
Deduplication identifies identical documents appearing more than once in a dataset. Removing redundant copies from review can prevent teams from spending time reviewing the same content repeatedly. However, teams must understand whether deduplication is global or custodian-based and preserve the metadata and relationships needed to establish where documents originated.
Email threading provides another opportunity to reduce review volume. It groups related messages in an email conversation and can identify messages that contain the substantive content of earlier emails. Reviewing the most inclusive message may reduce repetitive work, but earlier messages can still contain unique information, attachments, or contextual details.
Threading should therefore account for missing messages, unique content, and attachment relationships rather than treating every earlier email as unnecessary.
3. Search terms and conceptual analytics
Keyword searches can identify documents containing specific names, phrases, dates, or terminology associated with a dispute. Well-designed searches can be useful for narrowing a dataset, but poorly chosen terms may miss relevant documents that use different language or abbreviations.
Conceptual analytics can help identify documents discussing similar ideas even when they don’t contain the same exact words. Depending on the platform, these tools may organize documents into thematic groups, identify similarities, or surface related content that conventional searches might miss.
Search terms and analytics should be tested against known relevant documents and refined as the team learns more about the data. A document’s failure to match a search term does not, by itself, establish that it’s irrelevant.
4. AI-assisted document analysis
Generative AI adds another way to evaluate document content. Rather than relying exclusively on exact keyword matches, AI-powered tools can analyze documents against natural-language instructions describing the issues, information, or relationships relevant to a matter.
Relativity aiR Review uses generative AI to analyze extracted document text against defined criteria. It can help identify relevant documents, surface key evidence, categorize information by legal issue, and flag potentially sensitive business information. Its predictions include Rationale, Citations, and Considerations, meaning aiR will provide a rationale explaining why it’s predicting a specific value, then cite reasons why, and finally, will argue against itself and give reasons why it might not apply. In other words, aiR plays devil’s advocate against itself to help humans make the best possible judgement.
These capabilities can help legal teams prioritize important documents and identify information that conventional searches may not readily surface. However, AI is most effective when used within a human-in-the-loop review process. Experienced legal professionals help define the review criteria, evaluate AI-generated results, investigate discrepancies, and refine instructions when needed. By combining AI’s analytical capabilities with human judgment and quality control, teams can assess the reliability of results before using them to guide data reduction decisions.
AI-assisted analysis should never be treated as an automatic exclusion mechanism. Results depend on the review criteria, the documents being analyzed, and the quality of the validation process. Human oversight remains essential to identifying potential gaps, preserving relevant evidence, and maintaining a defensible approach to eDiscovery.
5. Sampling and technology assisted review
Sampling allows teams to examine a representative selection of documents to evaluate whether a filtering approach is working as intended. For example, a quality-control sample of excluded documents may reveal that a search term is missing relevant communications or that a date filter is too restrictive. As Burke explains, “Sampling establishes a baseline. When you understand the relevance rate, metrics like recall become much more meaningful.” This baseline helps teams assess the effectiveness of their approach and make more informed, defensible data reduction decisions.
Technology assisted review (TAR), including predictive coding, uses human input and analytical models to help prioritize or classify documents. While generative AI and traditional predictive coding use different approaches, both require a suitable workflow and an evaluation process appropriate to the matter. Sampling and quality checks help determine whether the results are reliable enough for their intended use.
TAR is not a substitute for sound legal judgment. The team should establish an appropriate validation approach, document its methodology, and assess whether the results meet the requirements of the matter.
How to Reduce Data Without Increasing Risk
Analytics can identify opportunities for savings, but a defensible process depends on how decisions are made, tested, and documented.
- Preserve first, then cull – Potentially relevant information subject to a preservation obligation must be protected. Filtering a working review dataset is different from permanently deleting source data. The team should maintain appropriate preservation measures and avoid treating an exclusion from review as permission to destroy evidence.
- Validate the criteria – Test proposed filters, search criteria, and AI-generated classifications against known relevant documents and examine samples of excluded data. When results reveal gaps, adjust the criteria before applying them more broadly.
- Maintain an audit trail – Document the filters, search terms, date ranges, deduplication settings, analytics methods, validation results, and significant decisions. This record helps explain the process if questions arise about the completeness of the collection or production.
- Reassess as the matter develops – New custodians, additional claims, deposition testimony, or newly discovered terminology may change the scope of relevant information. Culling decisions should be revisited when material facts or discovery requirements change.
- Keep human judgment central – AI predictions should inform decisions, not automatically determine which documents can be excluded. Reviewers must assess uncertain results, investigate potential gaps, and apply legal judgment to the evidence.
These practices reflect the broader principle that efficiency and quality are not competing objectives. A well-planned process can reduce unnecessary work while preserving the information needed to meet discovery obligations.
Balancing Cost, Completeness, and Compliance
Data culling is most effective when cost reduction is evaluated alongside the potential consequences of missing evidence. The least expensive approach at the beginning of a project may create greater expense later if important documents must be recovered, discovery must be repeated, or the production process is challenged.
“Reducing the review population is only valuable if you understand how you got there,” said Burke. “Whether you’re using filtering, searching, email threading, analytics, or TAR to reduce the population, you should also have a way to validate those decisions, including sampling where appropriate, and document the methodology behind them.”
The right strategy depends on the matter’s scope, the data involved, the available technology, and the legal team’s priorities. Experienced eDiscovery professionals can help evaluate these factors, select appropriate analytics, and establish quality checks that fit the project.
Ultimately, defensible data culling is about making informed decisions at every stage of eDiscovery. By combining targeted filtering, analytics, validation, and documentation, legal teams can focus review efforts on potentially meaningful evidence while managing costs and protecting the integrity of the discovery process.
Make Your eDiscovery Process More Efficient
The right data culling strategy can help your team manage review costs while keeping relevant evidence in focus. Avalon’s eDiscovery experts can help you evaluate your data, identify opportunities for effective reduction, and develop an approach that combines technology with experienced human oversight. Contact our team today to discuss your eDiscovery needs.